AI for Construction Documents
A spec book and a drawing set are some of the longest, most cross-referenced documents any industry produces. Getting AI to read them reliably takes more than a bigger model.
These posts cover the practical side — what it takes to run capable models on hardware you own, and how AI holds up on real engineering tasks — alongside the technical explainers on retrieval and context windows behind TeraContext.AI.
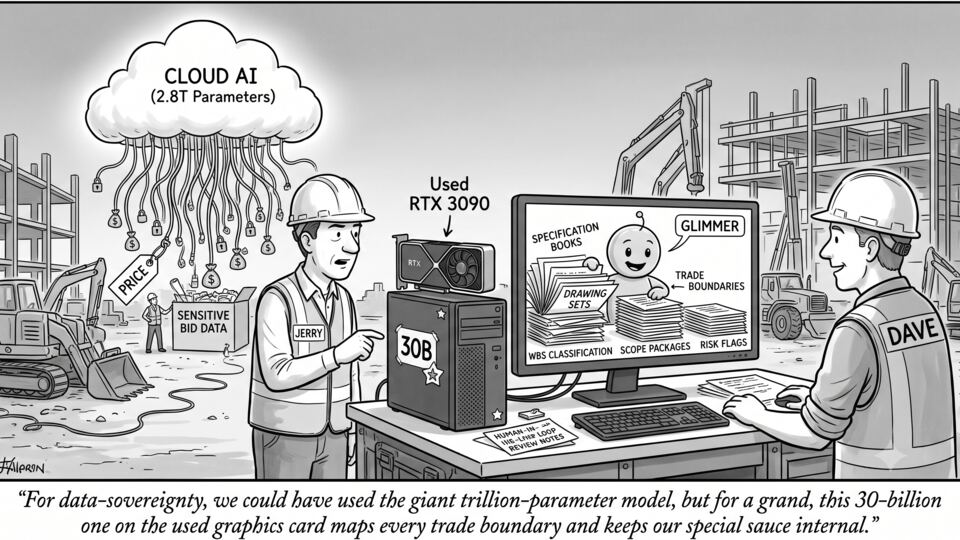
Own your model
Mid-sized models on your own hardware keep project documents in the building.
Field notes
What happens when AI is pointed at real engineering and design work.
-
 AI for Documents
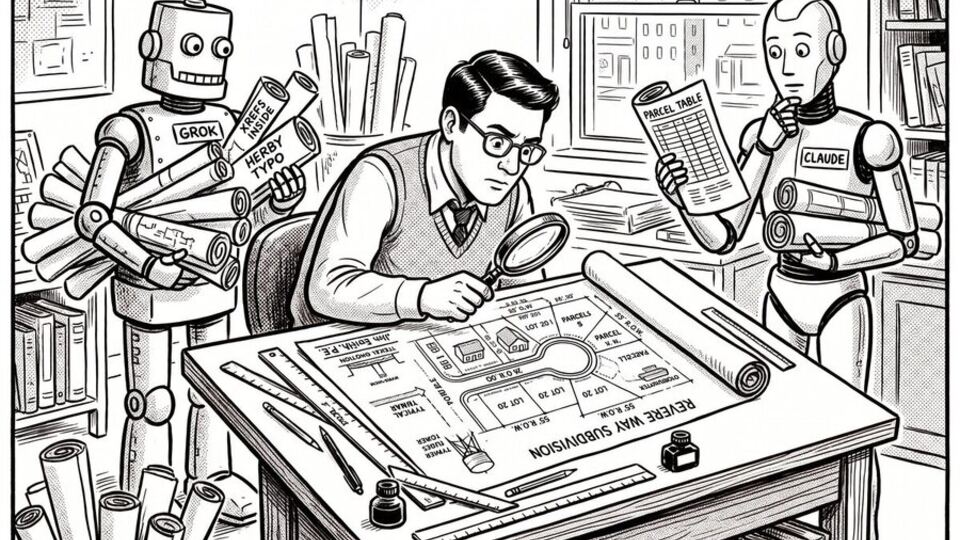
Two AIs, One Subdivision, Ninety Minutes
Grok and Claude each laid out a 20-lot Civil 3D subdivision from a one-line prompt in 45 minutes. One solved it; one only looked finished. What it means for engineers.
Read the post
- AI for Documents What Happens When You Let an AI Build Whatever It Wants I told an AI to build whatever it wanted, then left the room. It made a fantasy-map generator — and later gave those maps a thousand years of history. Read the post
How long-document AI works
Why a 2,000-page spec book doesn't simply fit in a context window, and the retrieval techniques that make it searchable.
- AI for Documents The Gambler - Managing Your RAG Mastering retrieval in RAG systems using semantic search, keyword search, graph search, and re-ranking—knowing what to throw away and what to keep. Read the post
- AI for Documents RAG vs. GraphRAG: Choosing the Right Approach for Your Documents Understanding the differences between RAG and GraphRAG, when to use each approach, and how to combine them effectively. Read the post
- AI for Documents RAPTOR and Multi-Layer Summarization: Building Hierarchical Document Understanding How RAPTOR and related multi-layer summarization techniques create hierarchical document understanding for more effective AI interaction. Read the post
- AI for Documents The Evolution of Context Windows: Why Bigger Isn't Always Enough LLM context windows have grown dramatically, but real-world documents still exceed these limits. Here's why and what to do about it. Read the post
- AI for Documents Why 1M Tokens Isn't Enough: The Mathematics of Context Windows A technical deep dive into why 1 million token context windows aren't as impressive as they sound—examining the mathematics, scaling challenges, and practical limitations of large language model context. Read the post
- AI for Documents Mamba vs Transformers: Rethinking Attention for Long-Context Processing How Mamba's state space models challenge transformer dominance for long-context workloads through linear-time complexity and selective attention mechanisms. Read the post